Why is GPU VRAM so much more important than regular RAM?
Running local AI is a memory-bandwidth bottleneck, not a raw compute problem. Every time a model generates a single word (or "token"), your system has to read the entire model—billions of parameters called "weights"—from memory.
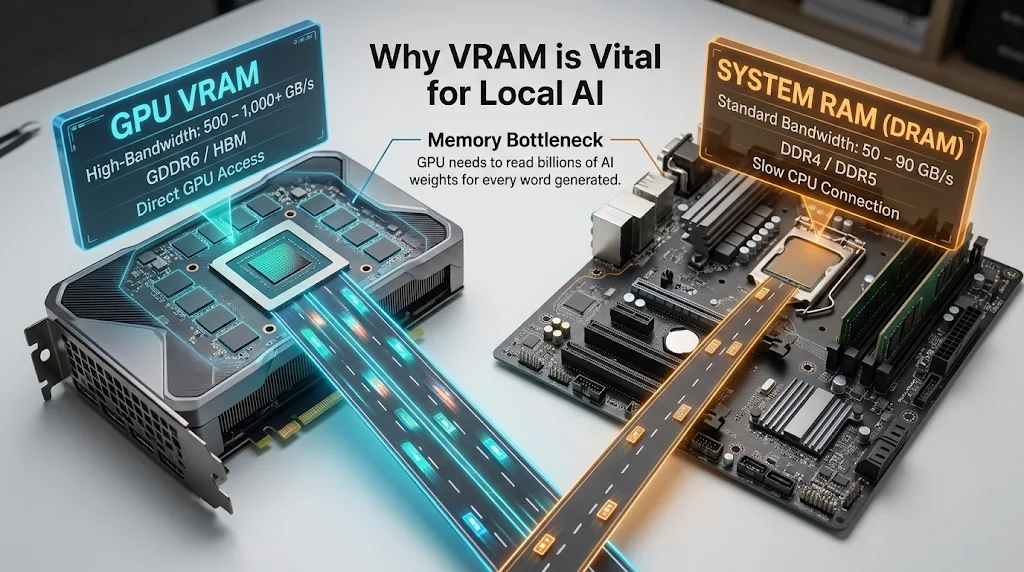
Think of memory bandwidth like the width of a motorway:
- GPU VRAM (The 20-Lane Superhighway): Dedicated graphics memory like GDDR6X sits right next to the GPU die and pushes data at 500 to 1,000+ GB/s. Because the chip can read the model almost instantly, words stream onto your screen faster than you can read them—typically 30–80+ words per second.
- Regular System RAM (The Single-Lane Country Road): Standard DDR4 or DDR5 motherboard RAM tops out around 50 to 90 GB/s—roughly 10x to 20x slower than VRAM. Forcing your CPU to haul a large model across system RAM creates an immediate bottleneck, dragging output down to a crawl at 2–5 words per second.
What happens when a model doesn't fit in VRAM?
Load a 10GB model onto an 8GB graphics card, and the remaining 2GB spills over into slow system RAM. That small overflow forces the GPU to stall and wait on the CPU for every single token, tanking generation speeds by 70–90%. That's why VRAM capacity is the spec that matters most when buying an AI rig: it sets a hard ceiling on the largest model you can run at full speed.
(Apple Silicon Macs are the exception here. M-series Pro, Max, and Ultra chips rely on high-speed Unified Memory running between 150 GB/s and 800 GB/s, letting the GPU chew through large pools of memory without a separate graphics card.)
Looking for verified hardware rigs?
Check our real-time £/GB VRAM index to find systems optimized for local model inference.